Below some of the ongoing research topics with a focus on either AI, Machine Learning, multi-agent systems, collective intelligence or complex systems. All this work is done with an excellent team of junior and senior researchers, highlighted on this page. If you are looking for publication information see; ULB Di-fusion, VUB Pure, ORCID, SCOPUS, Google scholar or DBLP

1. Machine learning applied to biomedical questions
a. From oligogenic data to predicting the pathogenicity of variant combinations
b. From knowledge graphs to gene pathogenicity predictions

2. Theoretical foundations of multi-agent systems
a. Delegating decision-making to AI
b. Evolution of cognitive mechanisms
c. Learning to solve cooperation problems with sparse rewards

3. Foundations of collective intelligence.
a. Algorithms for collective intelligence with expert advise
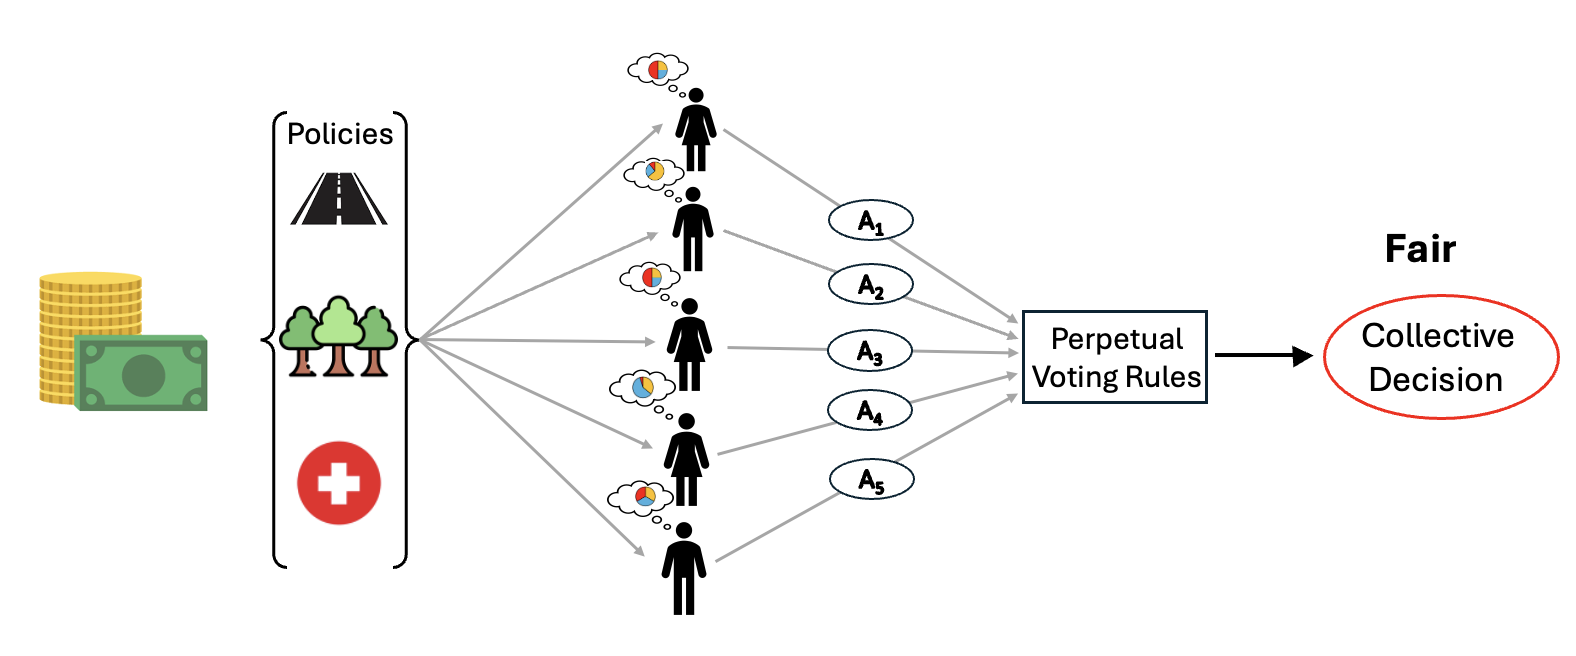
b. Artificial delegates may resolve fairness issues in perpetual voting

4. LLM-based agent modelling
a. How to model human values in LLM ?

Machine learning applied to biomedical questions

From oligogenic data to predicting the pathogenicity of variant combinations

This research line was initiated more than a decade ago and is still ongoing (on the right a little historical sketch). We ask what combination of variants explains a disease phenotype as identifying a single, very rare and highly impactful variant is often not possible (e.g. the heterogeneous nature of diseases, low penetrance, etc.).

To achieve this ambition new resources that aggregate all published data on oligogenic variant combinations and associated diseases were collected, first in DIDA and later in OLIDA (the oligogenic disease database). These resources allowed us to develop the first variant combination pathogenicity prediction methods (VarCoPP 1.0 and 2.0) and the first analysis platform ORVAL that can be freely used to explore patient VCFs.

In addition a new oligogenic prioritisation approach called Hop was developed. Hop combines VarCoPP with a random-walk algorithm on BOCK (our oligogenic knowledge graph) to rank the variant combination pairs in relation phenotype (and if possible panel) information. Hop is now available via the ORVAL platform or via a python package oligopipe.

All these resources are also provided as ELIXIR services and via bio.tools. We are now validating our predictive methods with the different national and international teams.

Machine learning applied to biomedical questions

From knowledge graphs to gene pathogenicity predictions

Biological and molecular knowledge is often organized as networks, with different elements—like genes, proteins, or diseases— connected based on how they interact or relate to one another. Knowledge graphs (KGs) build on this idea by combining many different networks and structured sources of information into one unified map. These networks help scientists visualize and understand complex systems in the body.

We constructed such a KG, called BOCK (Biological networks and Oligogenic Combinations as a Knowledge graph) that now consists of 157.872 nodes of 12 different types (Fig. on the left) and 2.766.169 edges of 20 different types.

This KG was used to build a high-quality white-box predictive method, called ARBOCK, to identify gene pairs that could potentially be related to an oligogenic disease. ARBOCK is a rule-based classifier that uses patterns extracted from paths connecting oligogenic genes to create rules which are then combined in a decision set classifier. The big advantage of this approach is that the results remain interpretable.

Our latest work in this line of research explored whether ARBOCK’s performance could be improved by using knowledge graph embeddings (KGE) as features for the prediction of gene-pair pathogenicity. The embedding method is called oli2vec and the new predictor GeCoPP, the Gene Combination Pathogenicity Predictor. An improvement in predictive power was observed, and we showed for known digenic combinations observed in a Male infertility cohort that the KGE approaches as well as ARBOCK outperform all alternatives suggested in literature (see image on the left).

Theoretical foundations of multi-agent systems

Delegating decision-making to AI

What is the effect fo delegating choices in strategic situations to algorithms or an AI system ? In the last years we have published a series of experimental and modelling paper on that topic.

In a first work, we experimentally analysed whether groups composed of artificial delegates (either predefined or self-configured) selected by human participants are more successful in deciding how to act in the collective risk dilemma. While the answer appears to be yes, as the AI or algorithm acts as a commitment device, we also saw more inequality in the gains between the participants. In a follow-up experiment, we further investigated the problem, introducing differences in choices and also a second stage of the same game, allowing participants to revise the "AI settings" or "program”. The results show that people who delegate are more likely to contribute to a public good and correct previous group failure by increasing their contributions when confronted with a new instance of the same game. However, precision errors limit the success of delegation groups.

An evolutionary game theory model aims to explain some of these results by considering how and when participants make mistakes, i.e. when they act themselves or when they code their agent in the wrong way or select the agent that is not matching their intentions. That model reveals that it may be better to delegate and commit to a somewhat flawed strategy, perfectly executed by an autonomous agent, than to commit execution errors directly.

A review of results in this area of reseach can be found in this paper entitled “Social physics in the agent of artificial intelligence".

Theoretical foundations of multi-agent systems

Evolution of cognitve mechanisms

Theory of Mind (ToM) is considered to be an asset for autonomous agents: Having the capacity to infer beliefs and intentions of others is often assumed to lead to better solutions, displaying more advanced intelligence, and thus a necessity for AGI. While the explicit implementation of ToM in agents for solving specific tasks is studied intermittently, it is not understood what conditions encourage agents to acquire and prefer ToM and what other effects it has on the agents' behaviour.

We have investigated, using evolutionary game theoretical models in which agents have strategies that incorporate ToM (or not), the conditions for the emergence of ToM. The model is based on k-level reasoning and the centipede game was used as it contains both uncertainty about future rewards and interdependency of choices (see Rusch et al 2020). The red dot in the figure on the left highligts the matching between the model and experimental data.

Interestingly the model observations align with observations in psychology research concerning the optimism bias in the human species and evolutionary research concerning the adaptiveness of human biases and the importance of self-deception and reality-denial for the humans species.

In a follow-up paper we also studied whether there is a preference for biased reasoning or not. Results show that a kind of “wishful thinking” mechansim, favouring optimistic forecasts of the behavior of others, dominates the evolutionary dynamics for higher selection strengths, while also reducing the reasoning sophistication (bottom image on the left)

Foundations of collective intelligence

Collective intelligence with expert advise

Experts may have different opinions, as we have seen during the COVID pandemic. So what decision to take based on biased and conflicting advices ? We examined algorithmic solutions to this problem drawing inspiration from contextual multi-armend bandits.

Collective decision-making with expert advice algorithms have mostly tried to find the best expert in the group and then used that expertise for the decision. Yet, real collective intelligence algorithms should go beyond the best expert in the group. We have proposed algorithms that achieve this goal both in the case of stationary and non-stationary experts.

As experts vary in their degree of expertise or biases, CDM approaches need to also handle such variations to avoid sub-optimal or discriminatory decisions against minority cases. A novel algorithm — expertise trees — was proposed that constructs decision trees enabling the learner to select appropriate models.

We experimentally evaluated the performance in a fake news experiment where participants needed to recognise true and false headlines, showing that true collective intelligence can be achieved with Experise trees. We moreover showed how language models perform in this experiment and demonstrated that the combination of both human and LLM responses lead to better decisions, obtaining wisdom from diversity.

Theoretical foundations of multi-agent systems

Learning to solve cooperation problems with sparse rewards

In multi-agent scenarios, one may want multiple agents to learn to coordinate their actions to cooperatively solve some problem. While different MARL algorithms have been proposed, their success very much depends on the availability of rewards signals to direct the learning process.

We defined a new problem called the laser learning environment or LLE, wherein rewards are only given for collecting a gem or reaching collectively the destination. Yet to achieve the latter they have to cross a field where coloured lasers may be blocking the way. Agents of the same colour as the laser can block it while others die. Yet no reward is given for blocking or passing a laser.

State-of-the-art MARL algorithms like VDN or QMIX (or even subgoal-finding approaches like HAVEN or MASER) are not successful in finding policies unless reward shaping (PBRS) or some human data is introduced. The zero-incentive dynamics and the interdependency of actions makes this an interesting problem for MARL and Agentic research.

Foundations of collective intelligence

Artificial delegates may resolve fairness issues in perpetual voting

Collective decisions are often made repeatedly over time, ranging from elections and online platforms to autonomous multi-agent systems. While popular rules like majority voting may be effective for one-shot decisions, they can systematically disadvantage minority groups in sequential decision-making, raising long-term fairness concerns. Fair collective decision-making should therefore go beyond aggregating preferences; it should also protect minority interests and preserve epistemic diversity. We investigate algorithmic solutions to overcome this ‘Tyranny of the Majority,’ i.e., to reduce majority dominance and improve long-term fairness.

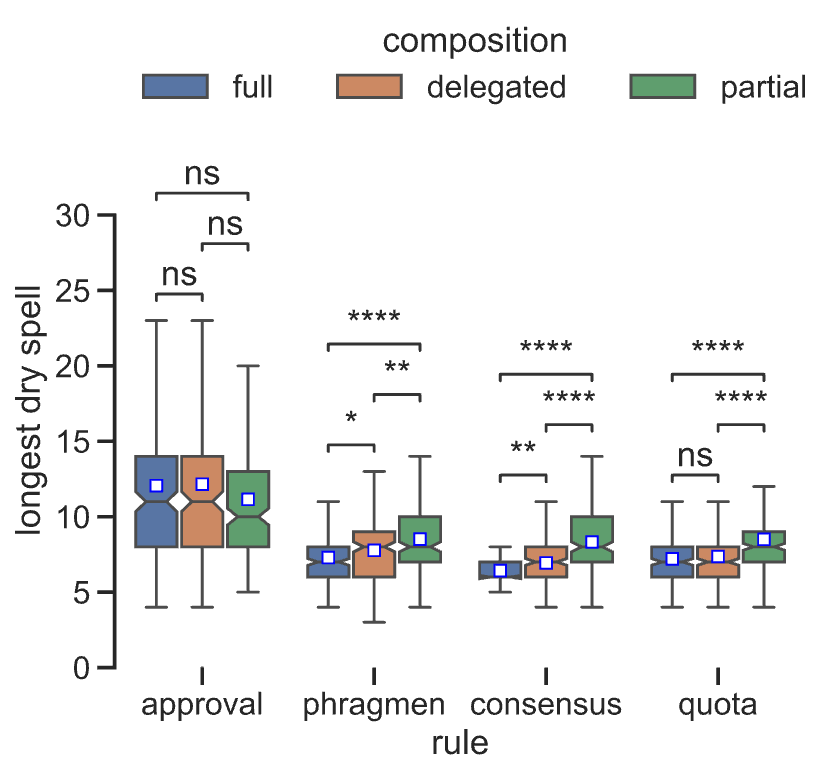
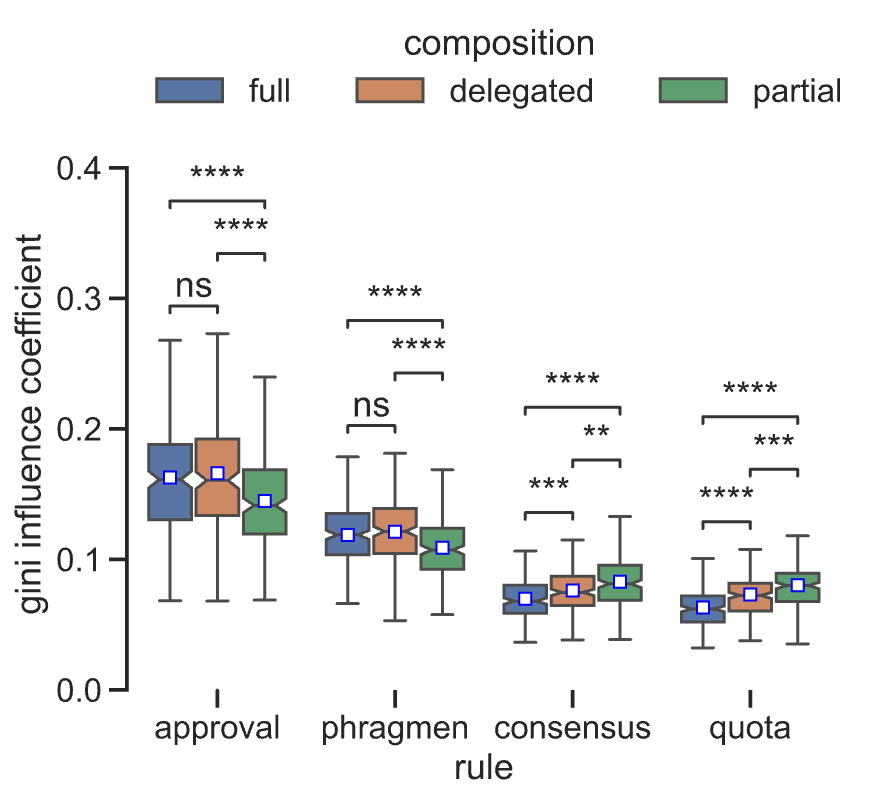
In our first study, we build on the concept of perpetual voting, a framework designed to ensure fairness across a sequence of collective decisions. We investigate its application to participatory budgeting, where citizens repeatedly decide how public funds should be allocated. Existing perpetual voting methods assume full voter participation, a condition that rarely holds in practice, where absenteeism is common. To address this challenge, we introduce Artificial Delegates, preference-learning agents trained to represent absent voters. Our results show that absenteeism substantially undermines fairness across different voting rules, but Artificial Delegates consistently mitigate these effects, improving both representativeness and robustness across a wide range of scenarios.

LLM-based agent modelling

How to model Human values in LLM ?

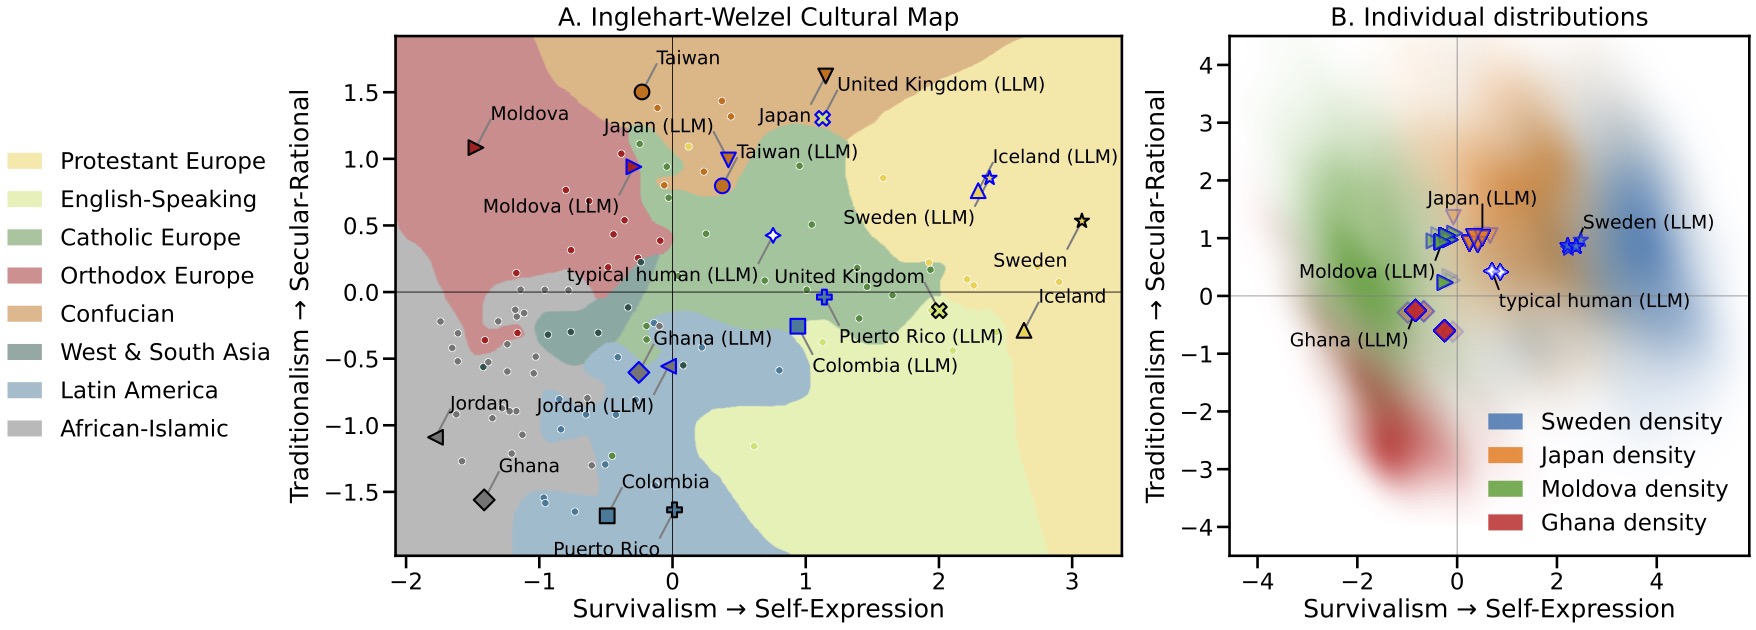
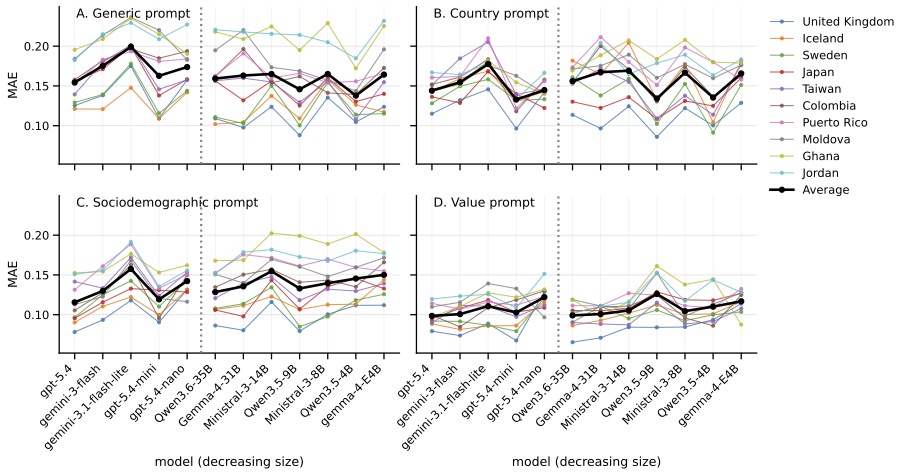
Large language models (LLMs) are increasingly used to simulate human opinions and survey responses, but their ability to reproduce population responses across cultures remains limited. Existing persona-based prompting methods typically rely on sociodemographic or personality traits, which are only indirect proxies for the values that shape human responses.

We proposed a value-based persona construction method that derives textual descriptors from survey responses capturing core cultural dimensions. By sampling value profiles from target populations and aggregating LLM responses across personas, we obtain population-level predictions grounded in observed value distributions.

We further introduced a calibration procedure that improves response diversity while preserving estimated opinions. We showed that our approach reduces prediction error across countries, with the largest improvements observed in underrepresented populations.

This substantially narrows the performance gap between countries aligned with dominant LLM priors and those that are less represented in training data, while also yielding response distributions that closely match human diversity.